LDaCA at the Zenadth Kes Language Symposium 2026
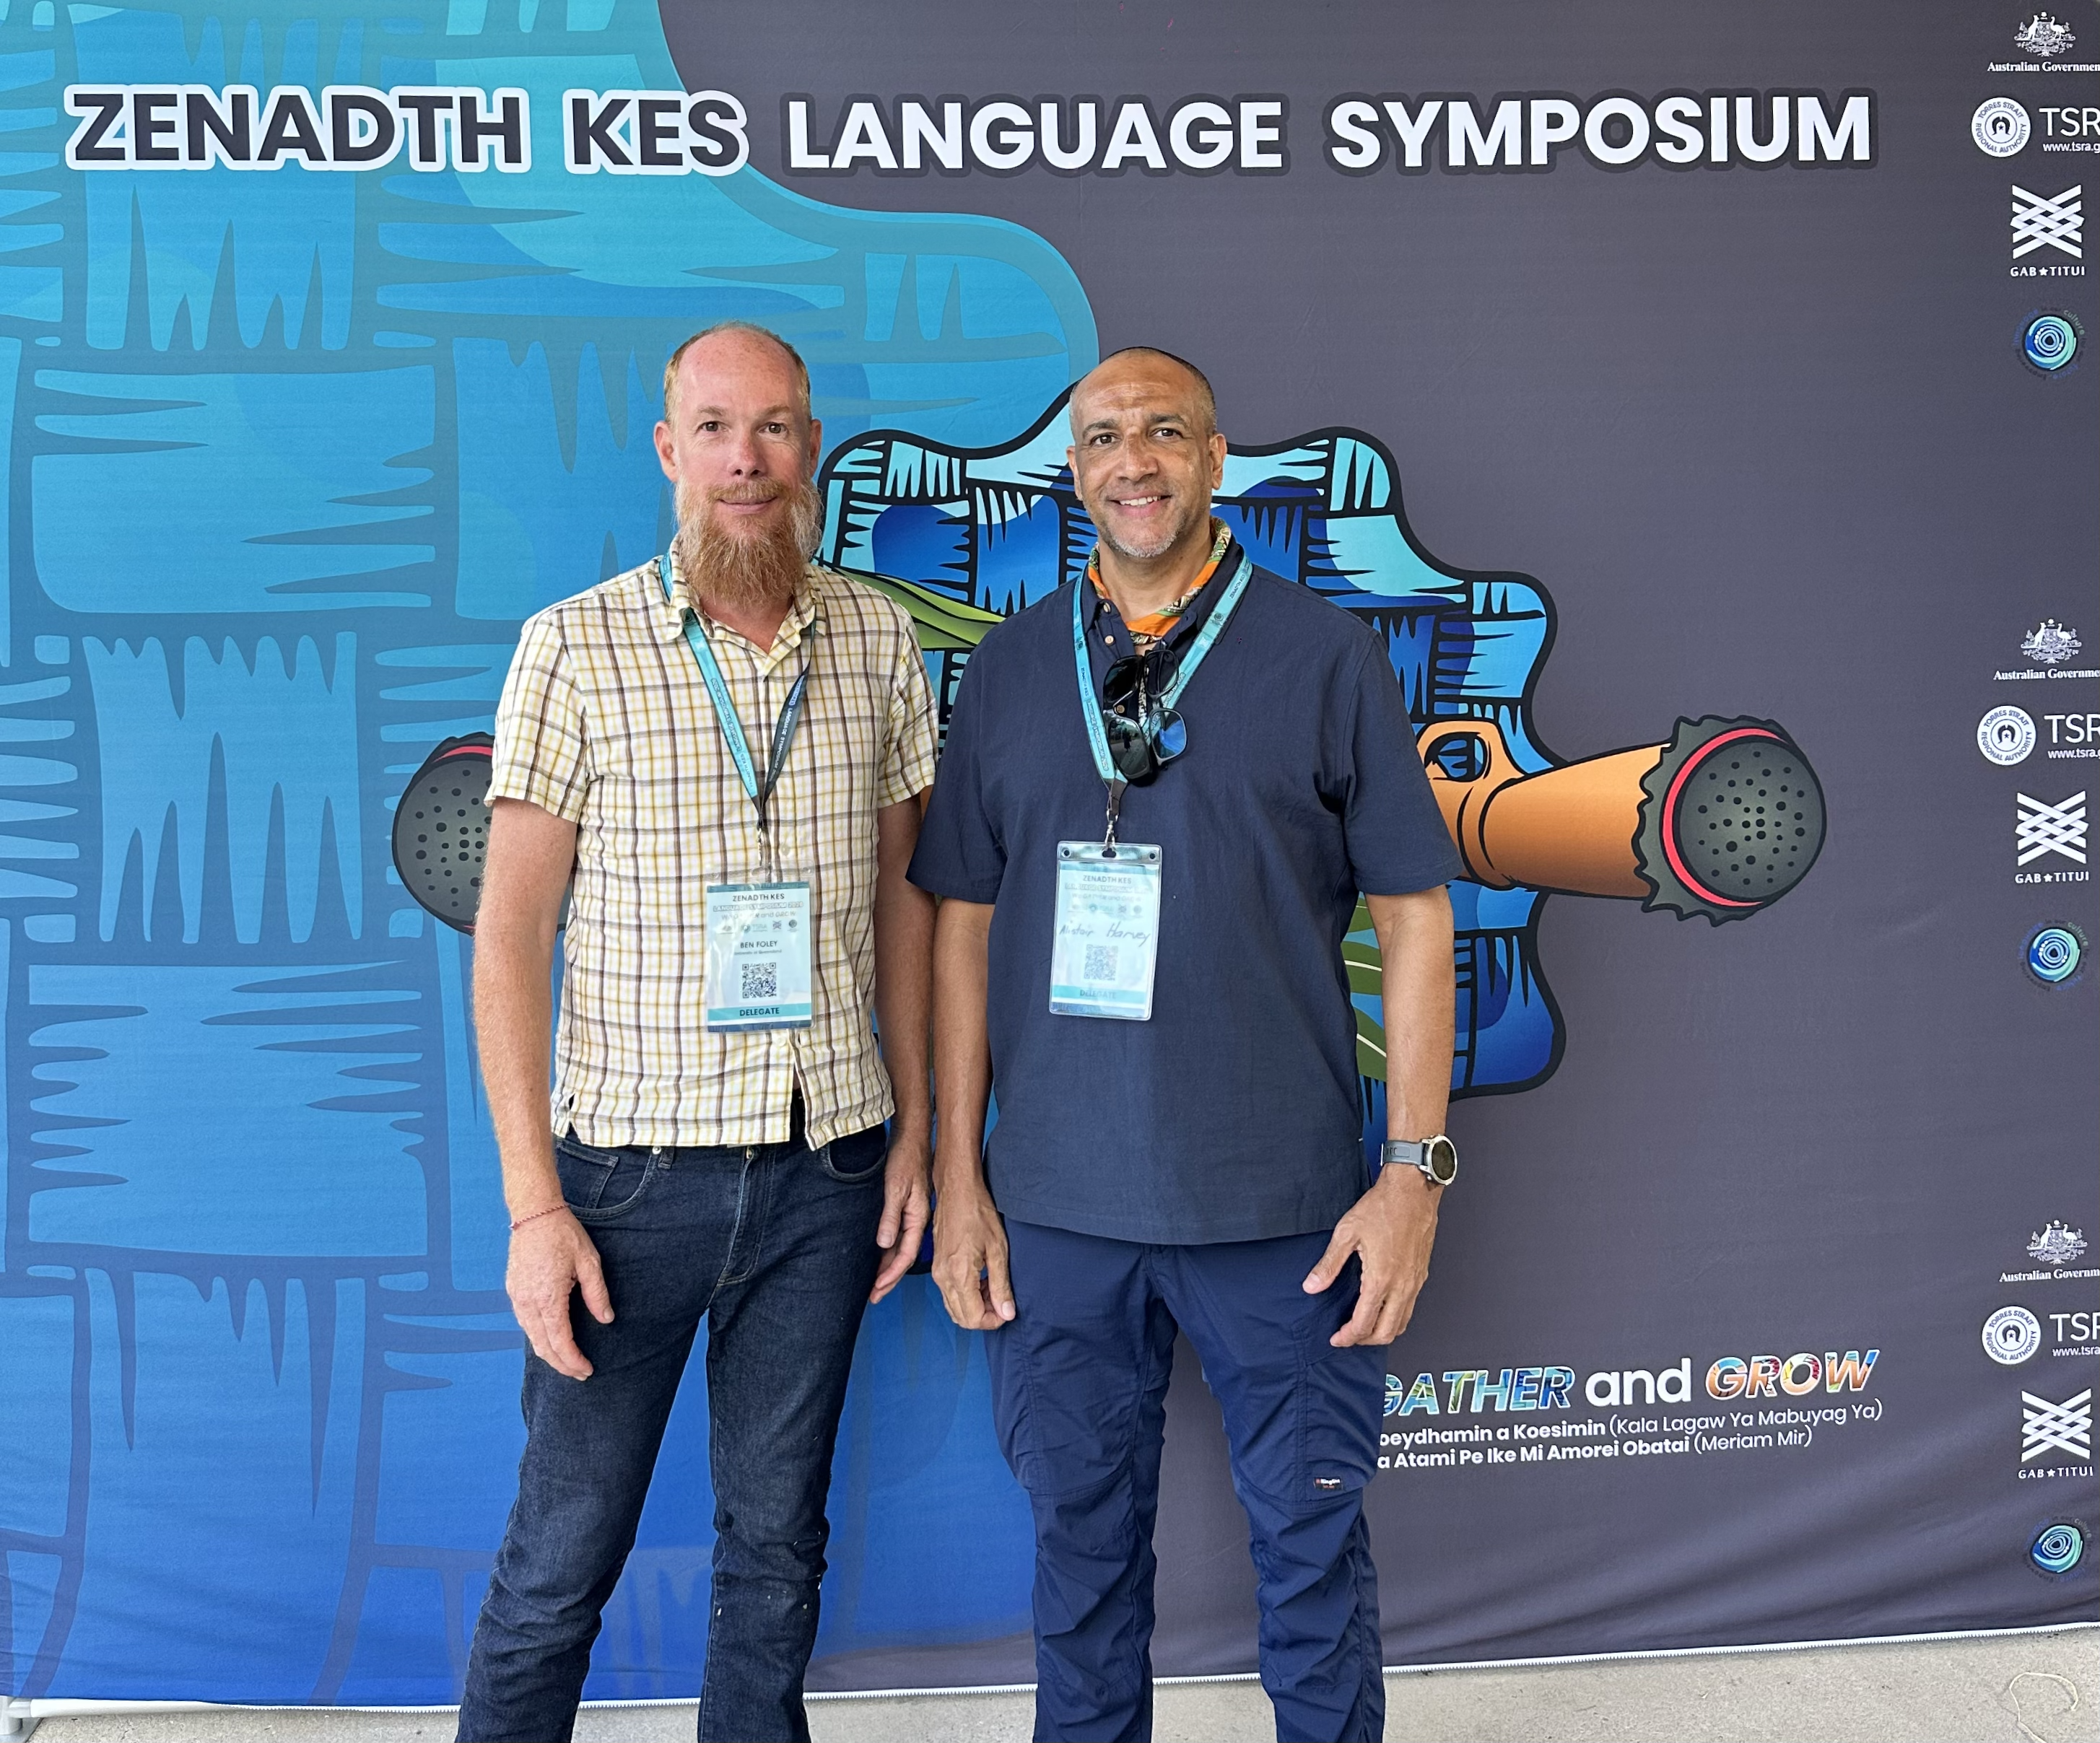
Read about LDaCA team members Alistair Harvey and Ben Foley's presentation at the Zenadth Kes Language Symposium in Thursday Island, focusing on community engagement and community archiving projects.
Read blog posts written by members of our team about the Language Research domain.
Read about LDaCA team members Alistair Harvey and Ben Foley's presentation at the Zenadth Kes Language Symposium in Thursday Island, focusing on community engagement and community archiving projects.
An update on the future plans for the Precarious Oral Histories project
Meet our newest Industry Fellow, Al Harvey, and learn about his work with community archives.
We invited several of LDaCA's Chief Investigators, Advisors and collaborators to reflect on the NAIDOC Week 2026 theme.
ARDC intern Blanche Alexander reflects on her experience at the AIATSIS Summit 2026.
What is it actually like to take part in LDaCA's Graduate Digital Research Fellowship (GDRF)? We put the question to Teresa Chan, LDaCA’s Senior Research Project Officer in Research Support and Training and a 2026 GDRF participant.
Language Technology Analyst Rosanna Smith shares advice for using regular expressions to refine search queries.
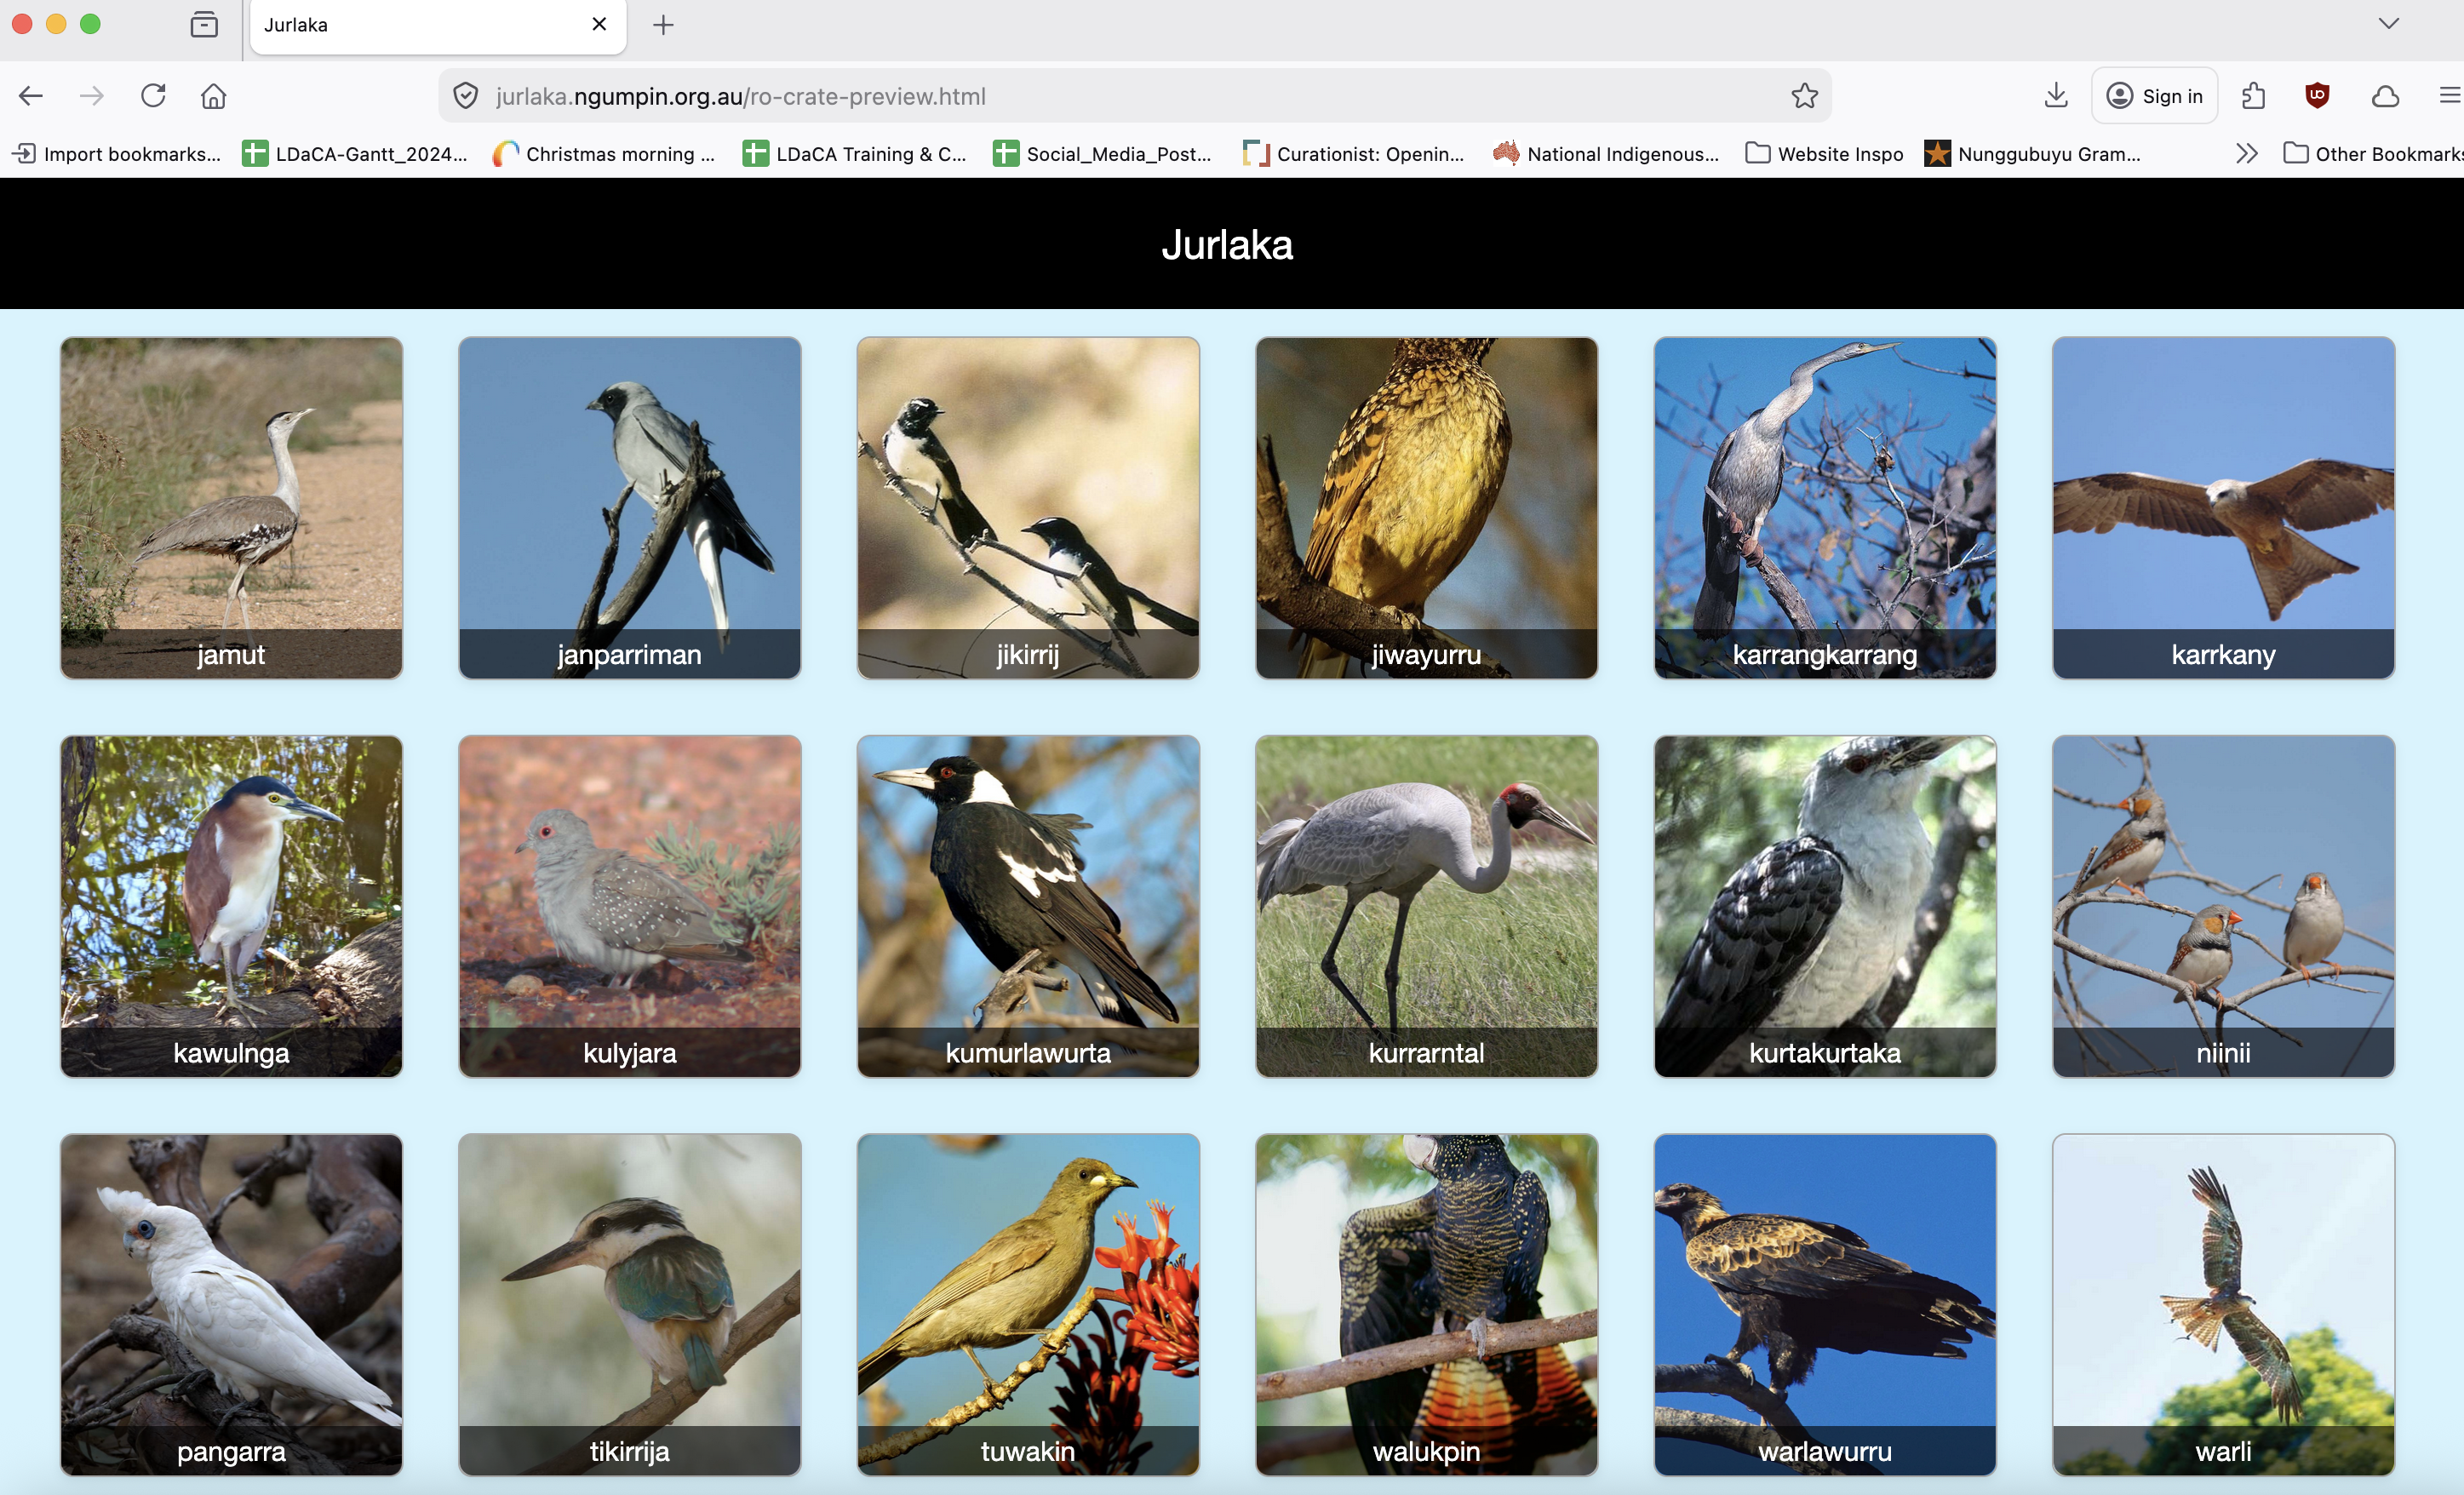
Read about LDaCA's involvement in the publication of four new Gurindji plant and animal websites, converting data from a poster project into RO-Crate format to build static sites.
A closer look at the AusReddit searchable aggregate data — a new collection on the LDaCA data portal — and what it offers researchers.
A closer look at the Australian Twittersphere searchable aggregate data — a new collection on the LDaCA data portal — and what it offers researchers.
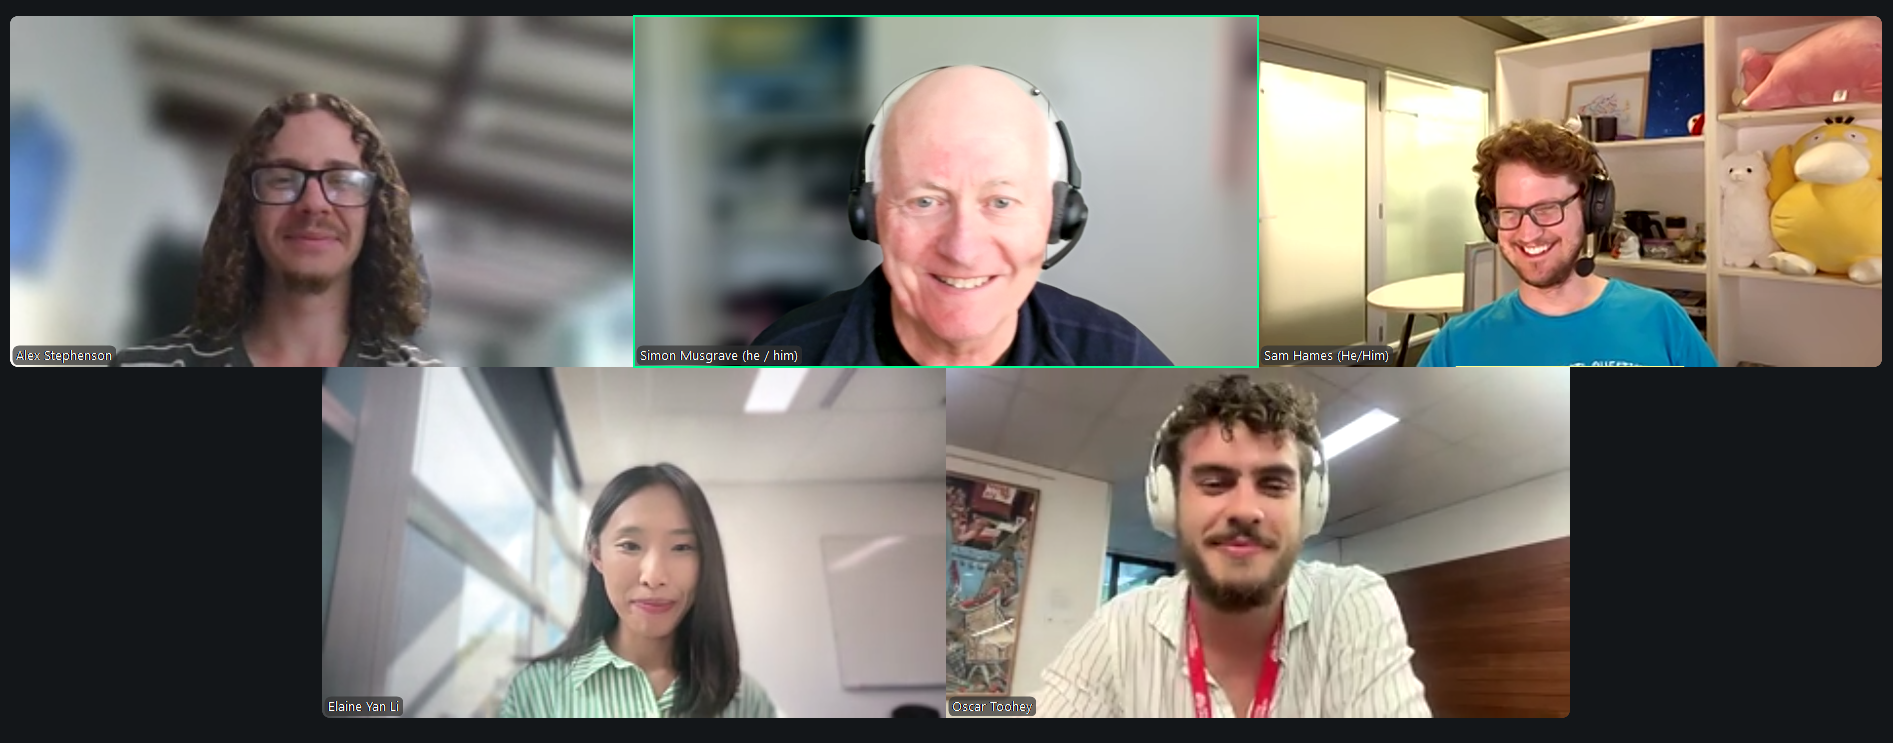
A blog post about the 2025 Graduate Digital Research Fellowship cohort, co-ordinated by Sam Hames (Research Analytics Lead) and Simon Musgrave (Research Support and Training Lead).
The Australian Slang Survey asked participants about expressions they thought of as typically Australian. Language Technology Analyst Rosanna Smith and Research Support and Training Lead Simon Musgrave worked to make this dataset FAIR compliant and publish it on the LDaCA Data Portal.
LDaCA is assembling a working party of those in our network using AI in their research. We intend to release advice covering particular AI systems, to be used as a guide for creating and working with language data using AI.
Learn more about how Research Analytics Lead Sam Hames and University of Queensland student Jasper Chong developed the Image Dataset Explorer, a tool for making sense of large image collections. Their work revealed insights that can also be applied to working with text.
Discover how we have been working towards implementing PILARS — the Protocols for Implementing Long-Term Archival Repository Services — by adopting open standards, building clear governance mechanisms and designing infrastructure that communities can trust and control.
Research Analytics Lead Sam Hames shares some advice for making sure that the data you’re working with suits your purposes.
Read about one of the first collections to enter our data portal — the Mitchell and Delbridge speech of Australian adolescents corpus (1959–1960) — and its impact on Australian linguistic research.
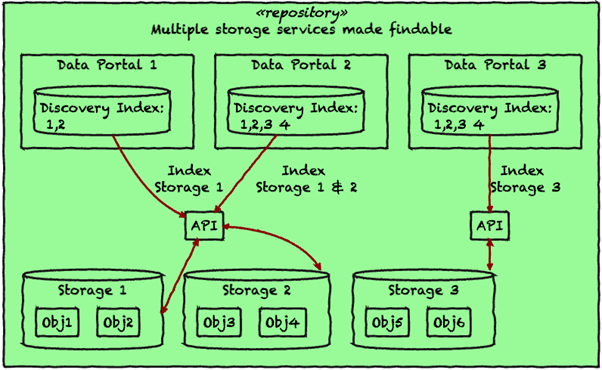
Refresh your knowledge of the principles behind our technical architecture and discover some recent developments, including how we are harmonising the open source tools used across our network of collaborators.
While corpus linguists might agree that data sharing is preferable, the use of copyrighted data imposes serious limitations. What options do linguists have for sharing these corpora outside their research team? Chief Investigator Monika Bednarek (University of Sydney) discusses this question.
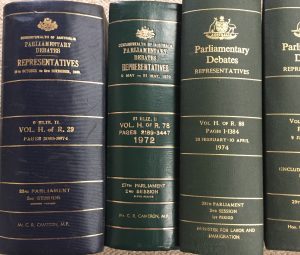
Learn more about the challenges of working with an unwieldy data source — the Australian Federal Hansard — from Simon Musgrave. In the blog post, Simon unpacks approaches to issues of access and scale allowing for the effective use of this data source.
Industry Engagement and Communications Lead Chenoa Pettrup draws on her past work as a graphic designer to suggest some starting points for turning your data into useful visuals.
Find out five ways Research Object Crates (RO-Crates) can support data stewards and why LDaCA uses RO-Crates in our infrastructure.
Chief Investigator Nick Thieberger (University of Melbourne) discusses storage and archival practice at PARADISEC, dialogic archives and the future of long term storage.
Data Migration Developer Mark Raadgever draws on his extensive experience with data migration to outline some important metadata principles. Consistency is key!
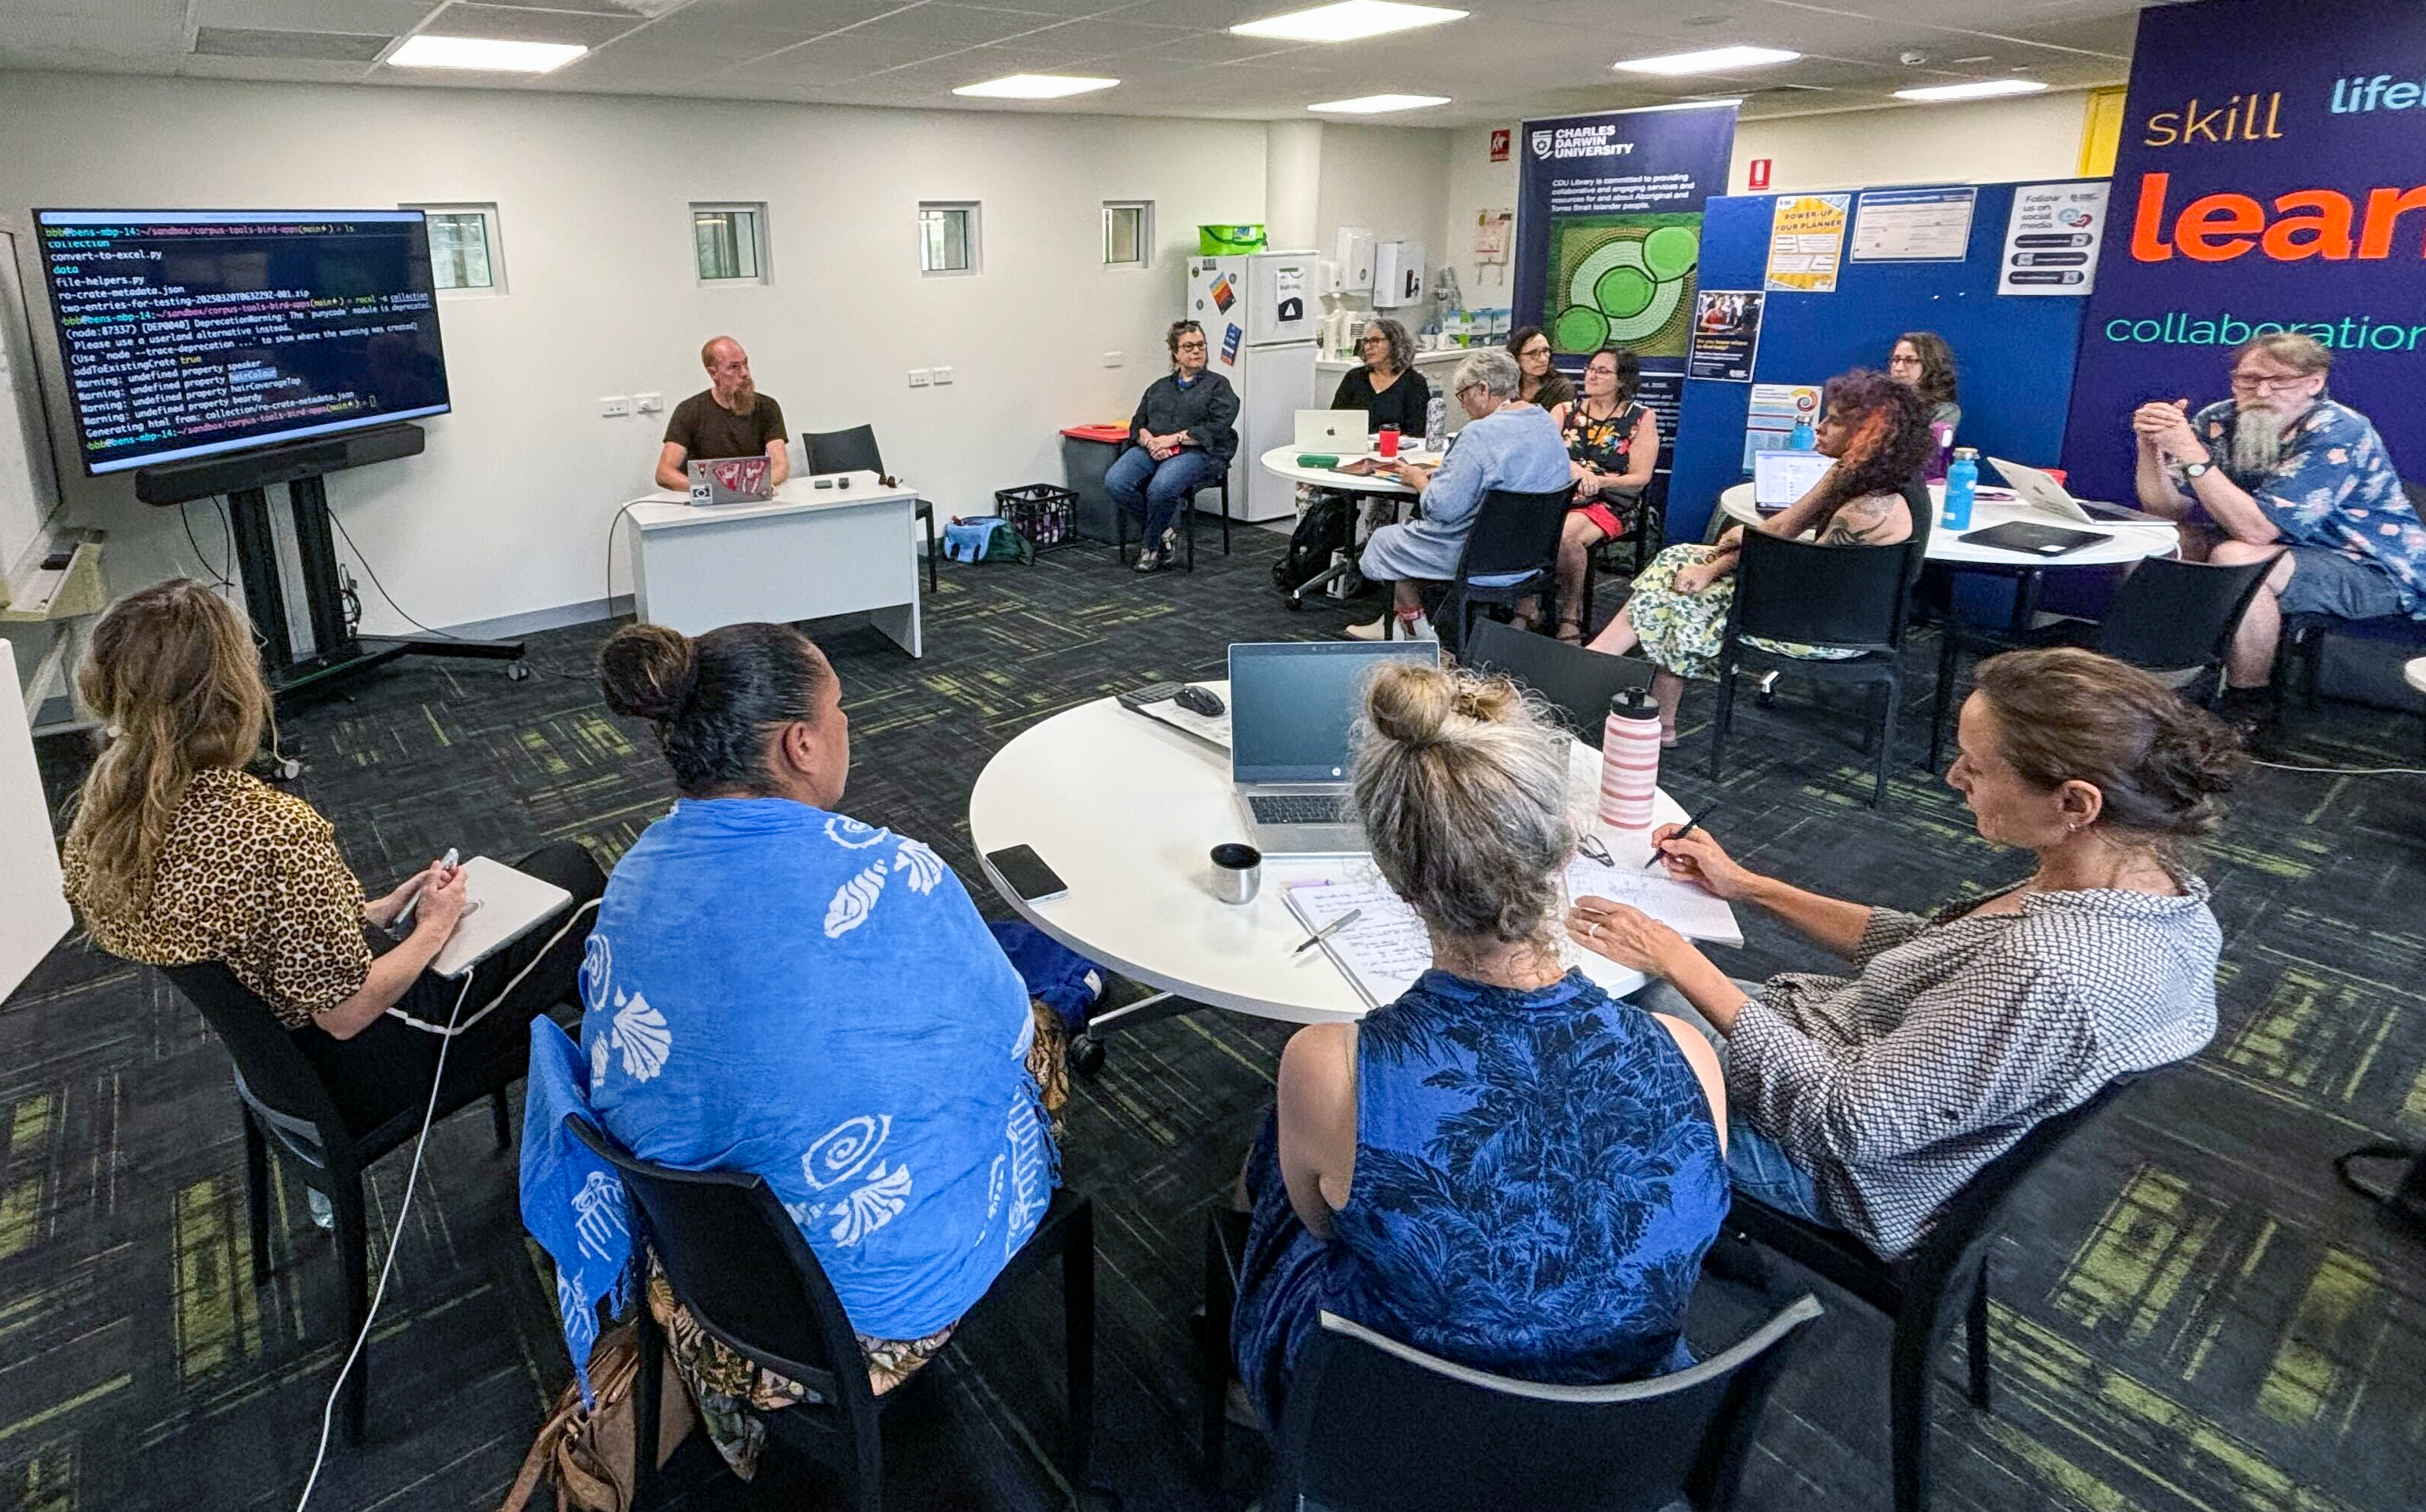
From 24–28 March, the LDaCA team hosted the Darwin digital languages collections workshop. This event brought together organisations and individuals from the Top End to exchange ideas and insights about Indigenous language collections and explore collaborative opportunities.
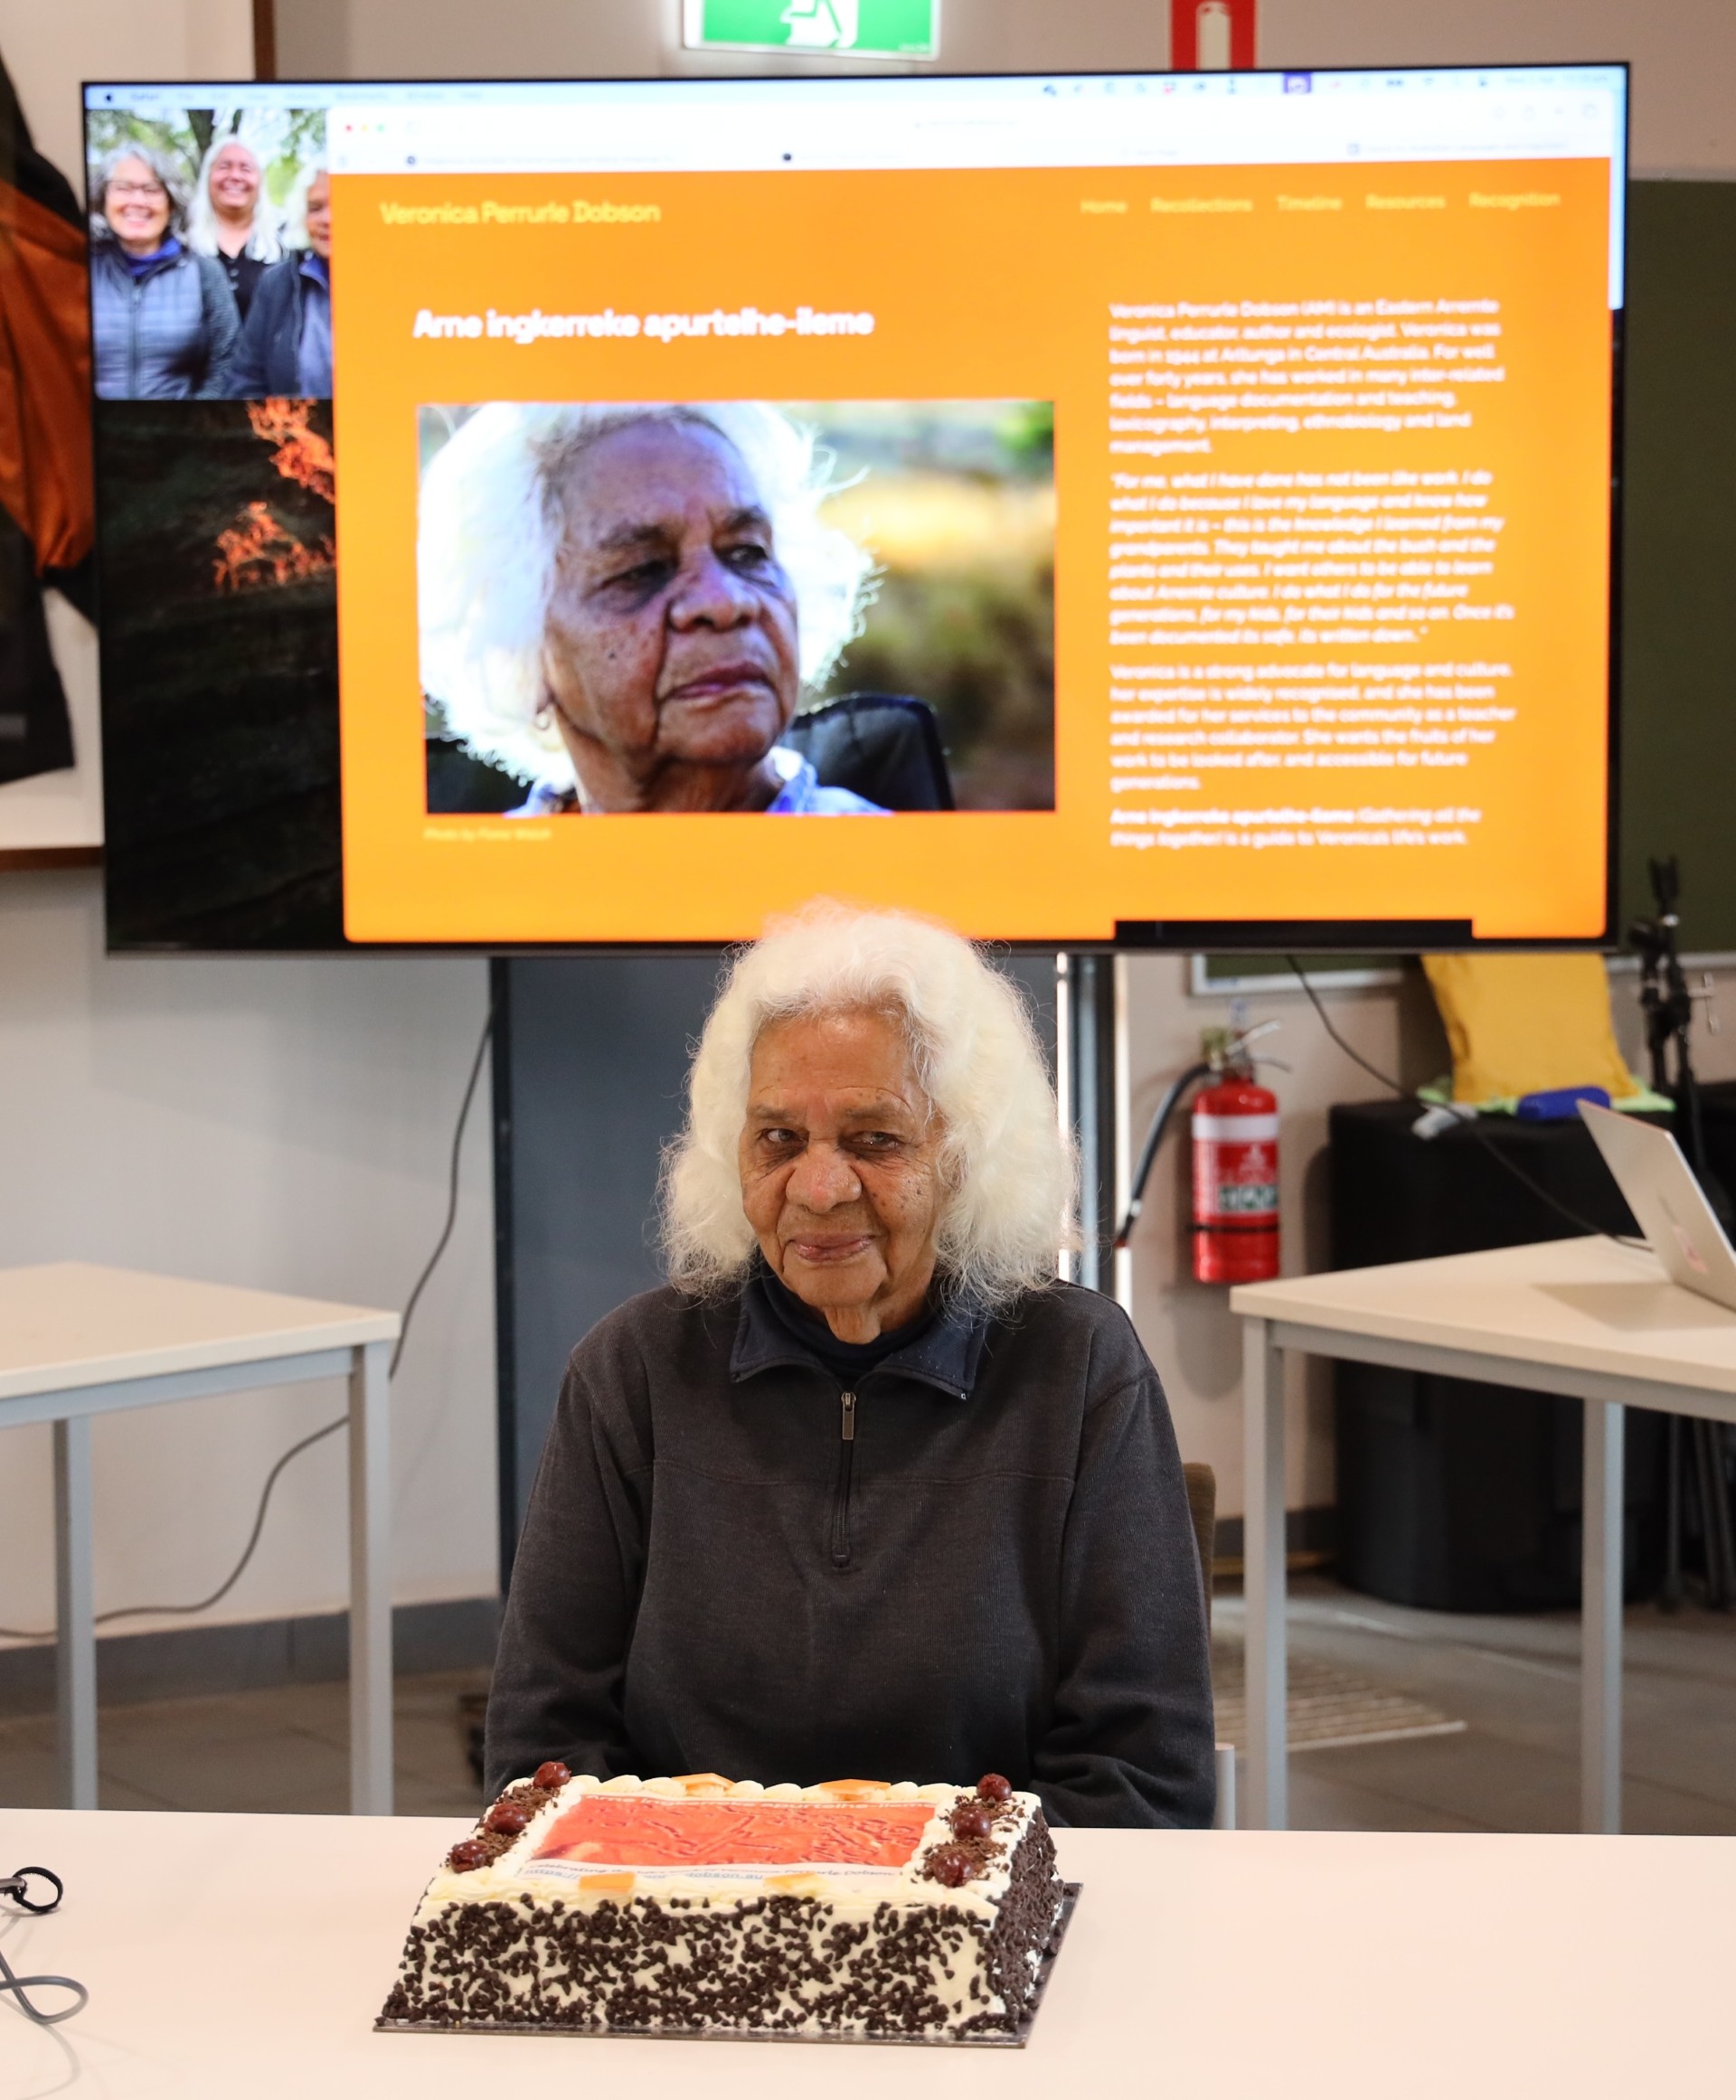
Read about the launch of Arne ingkerreke apurtelhe-ileme, sharing the remarkable life’s work of Veronica Perrurle Dobson AM.
Research Support and Training Lead Simon Musgrave discusses how he used four collections from the LDaCA portal to strengthen his argument in a recent publication that there is a tradition of Australian writers inventing expressions which they treat as being part of Australian slang.
Robert McLellan, Senior Program Manager for LDaCA, and Jenny Fewster, Director, HASS and Indigenous Research Data Commons for the Australian Research Data Commons, draw upon their collaborative work on CAREful FAIRness and Principles for Indigenous Data Governance.
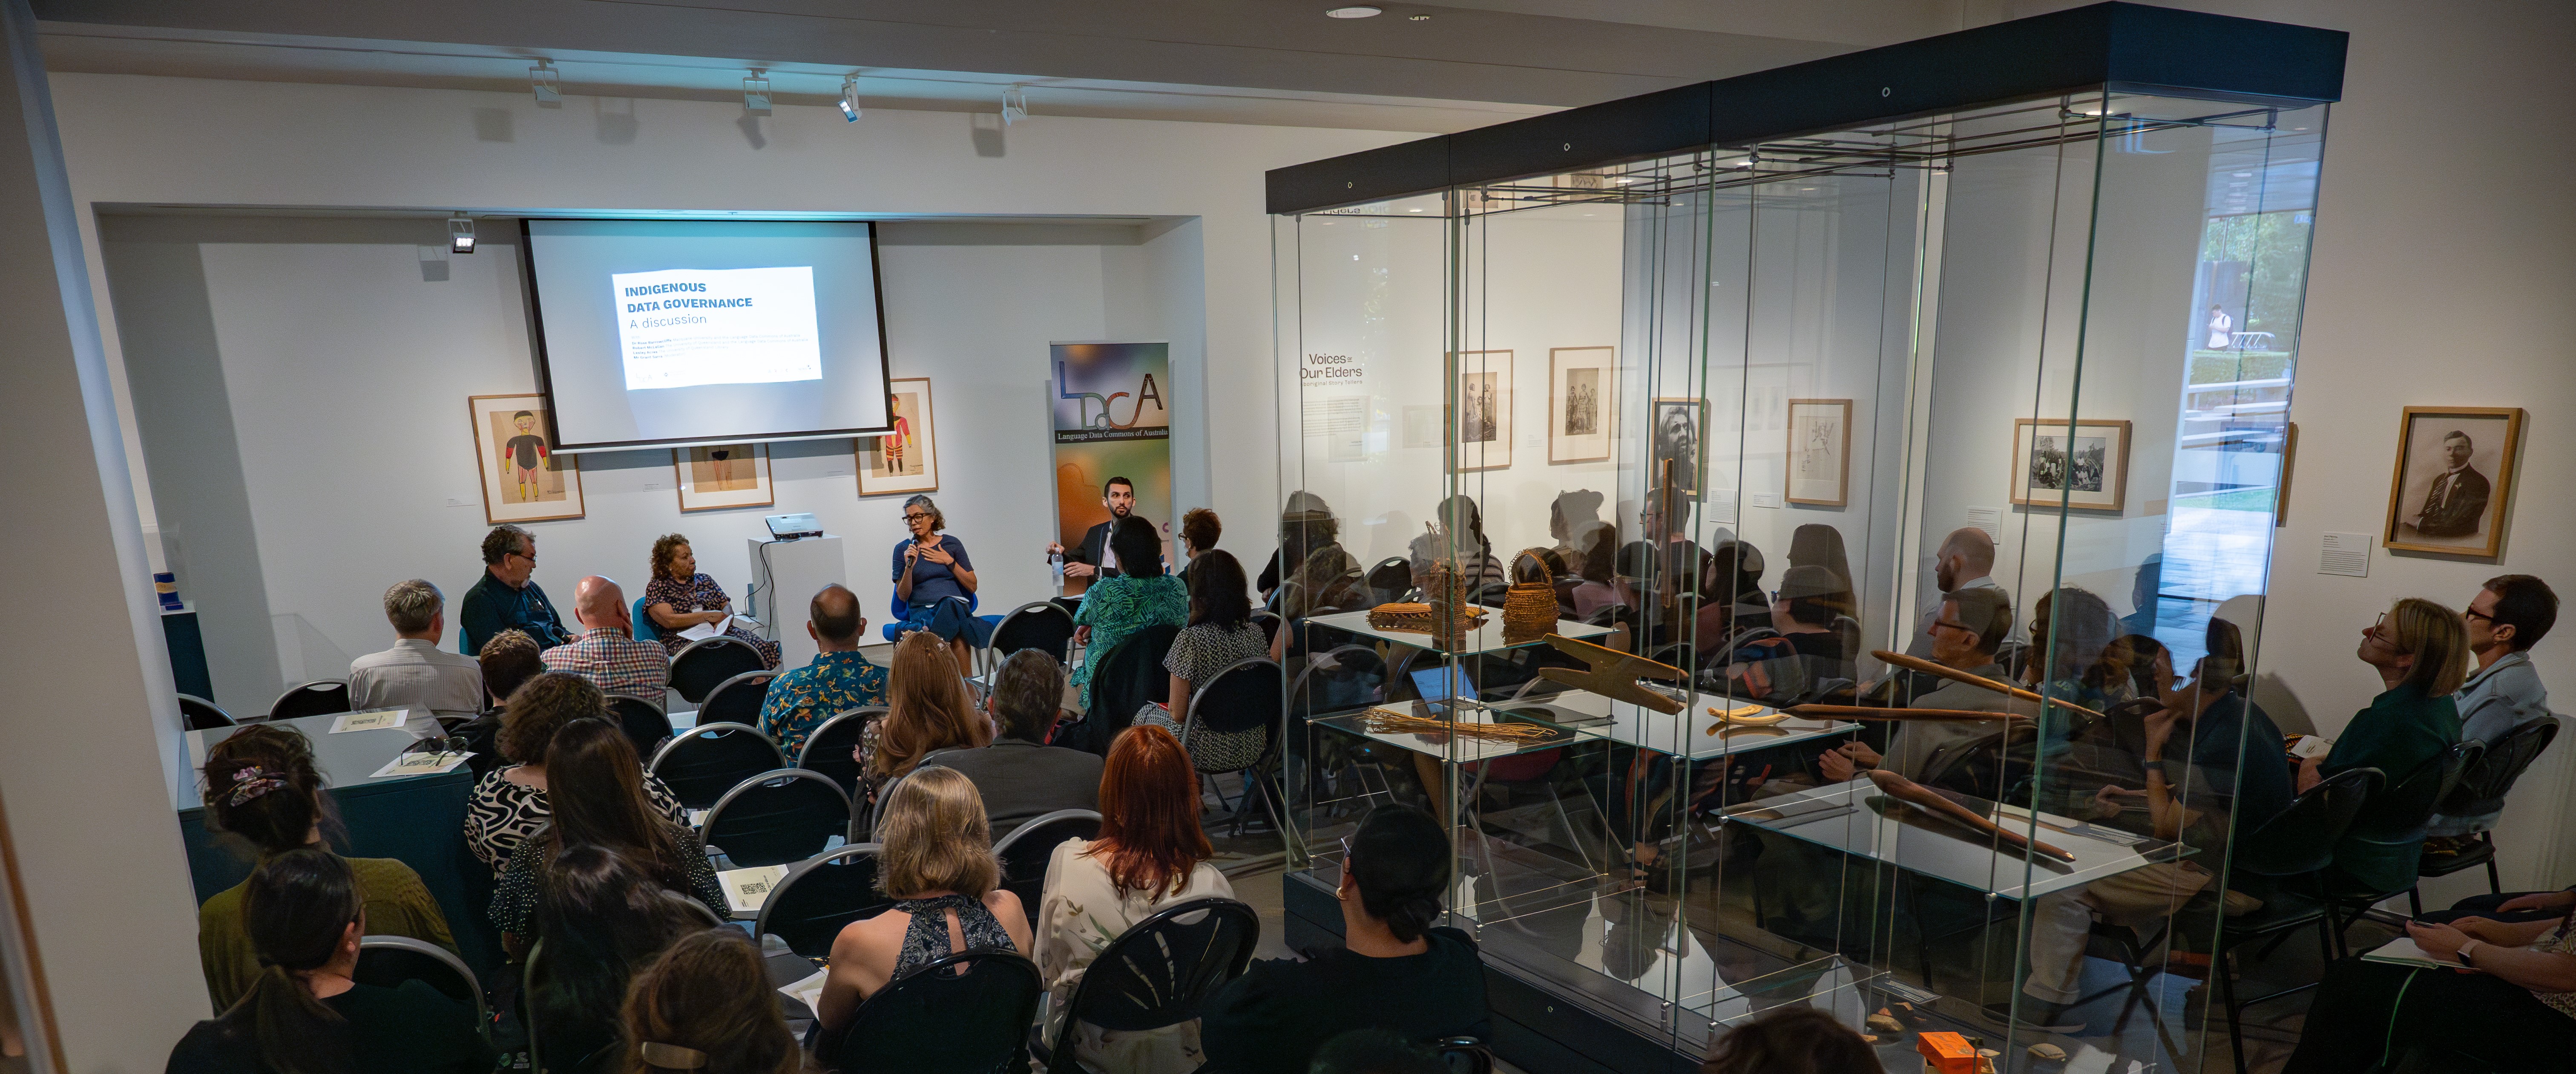
Read a summary of our learnings from the LDaCA-hosted Indigenous Data Governance panel discussion, which brought together three speakers — Lesley Acres (UQ Library), Dr Rose Barrowcliffe (Macquarie University and LDaCA), and Robert McLellan (UQ and LDaCA).
Jane Simpson, Professor Emerita at the Australian National University, discusses storing language data, obstacles to its long-term storage, her interest in making dictionaries accessible and how researchers at the end of their careers should manage data.
A blog post about the 2024 Graduate Digital Research Fellowship cohort, co-ordinated by Sam Hames (Research Analytics Lead) and Simon Musgrave (Research Support and Training Lead).
LDaCA Senior Data Manager Dr Julia Colleen Miller discusses her experience in archiving and data management for cultural heritage data.
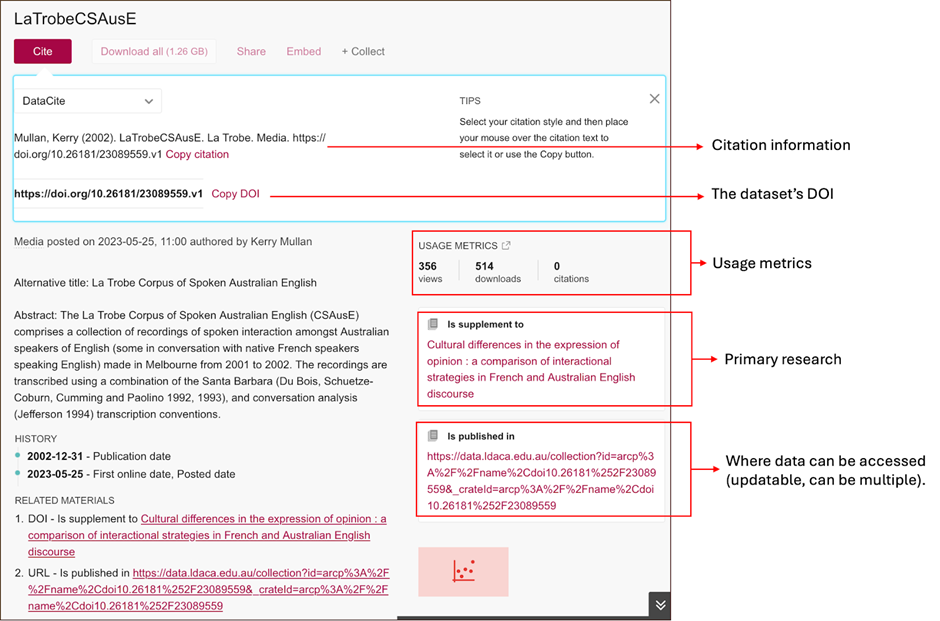
Persistent Identifiers (PIDs) and Digital Object Identifiers (DOIs) provide a universal, machine-readable, interoperable method to uniquely identify research outcomes and resources so that they are easily findable.
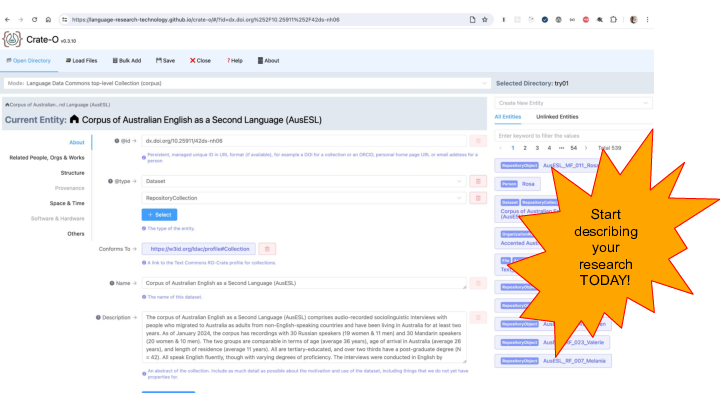
PT (Peter) Sefton attended the 19th International Conference on Open Repositories (3–6 June 2024, Göteborg, Sweden). With various collaborators, PT gave three presentations which are now available as blog posts: this post discusses Crate-O.
PT (Peter) Sefton attended the 19th International Conference on Open Repositories (3–6 June 2024, Göteborg, Sweden). With various collaborators, PT gave three presentations which are now available as blog posts: this post discusses RO-Crates.
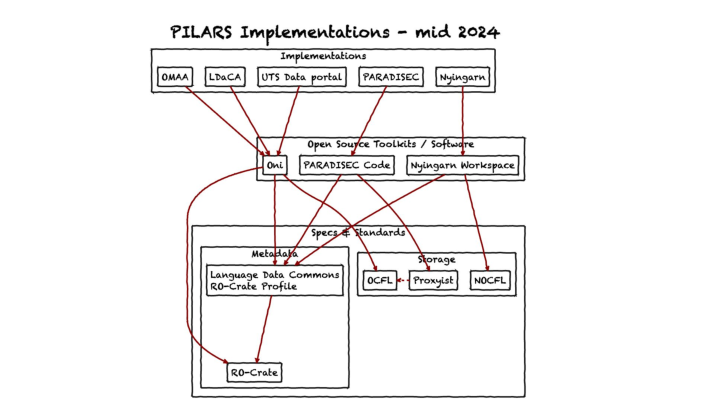
PT (Peter) Sefton attended the 19th International Conference on Open Repositories (3–6 June 2024, Göteborg, Sweden). With various collaborators, PT gave three presentations which are now available as blog posts: this post discusses PILARS.
A blog post discussing LDaCA’s thoughts about the Voices of Country Action Plan, a framework to guide Australia’s participation in the International Decade of Indigenous Languages, focusing in particular on Aboriginal and Torres Strait Islander community needs.
An interview with Kalin Stefanov (ARC DECRA Fellow at Monash University) about his work on an Australian Sign Language (Auslan) project.
LDaCA team members, who also worked on the AusNC project, explain the relationship between the two, and why AusNC is not an entity in the LDaCA Data Portal.

A blog post about the 2023 Graduate Digital Research Fellowship cohort, co-ordinated by Sam Hames (Research Analytics Lead) and Simon Musgrave (Research Support and Training Lead).
An interview with some former and current LDaCA Chief Investigators. This blog post features Catherine Travis (Australian National University), Monika Bednarek (University of Sydney) and former Chief Investigator Nicholas Evans (Australian National University).
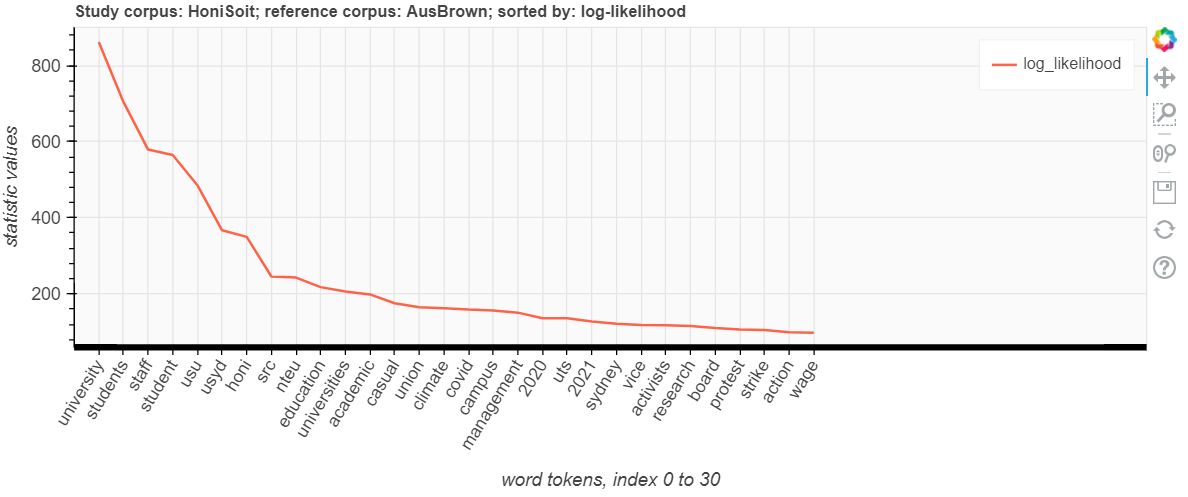
The Keyword Analysis tool is a Jupyter notebook containing code that was developed by the Sydney Informatics Hub (SIH) in collaboration with the Sydney Corpus Lab.
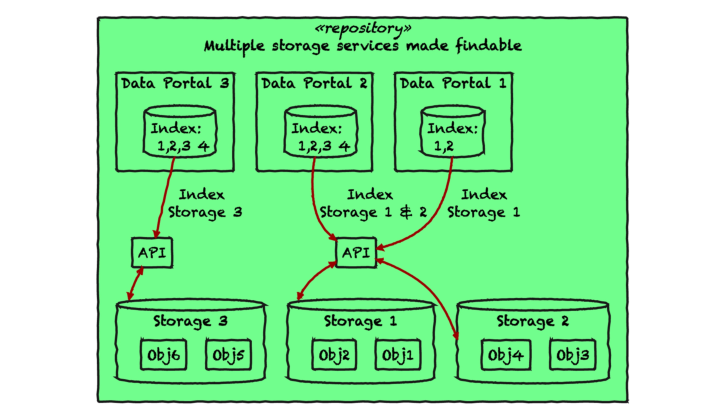
A presentation delivered by Peter Sefton at the Open Repositories 2023 conference in South Africa on 14 June 2023 in the Presentations: Discipline specific systems with FAIR principles session.
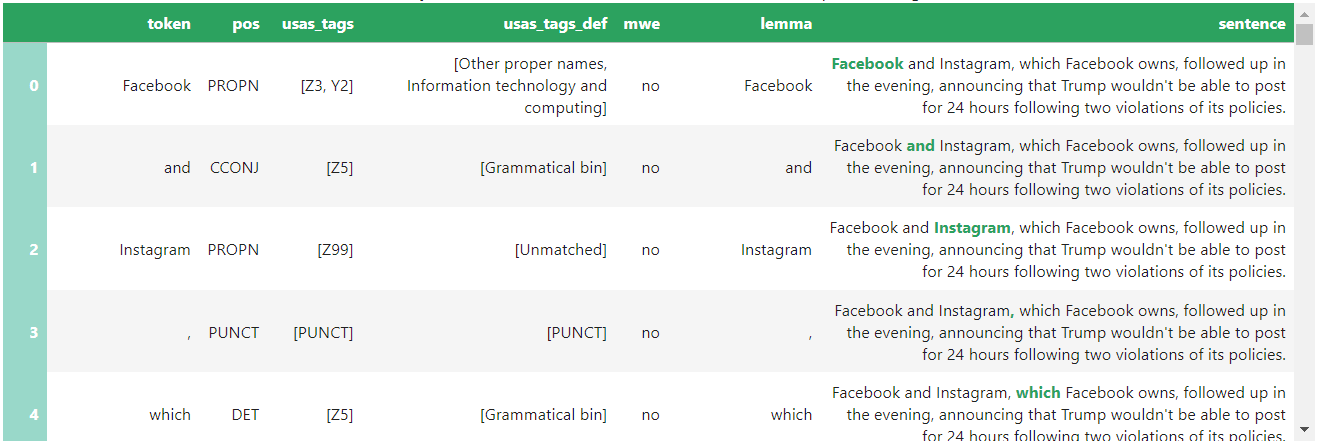
Introducing the Semantic Tagger tool for automatically categorising and annotating words or multi-word expressions in English, Chinese, Italian or Spanish texts.
An interview with some former and current LDaCA Chief Investigators. This post features Martin Schweinberger (University of Queensland), Nick Thieberger (University of Melbourne) and former Chief Investigator Louisa Willoughby (Monash University).
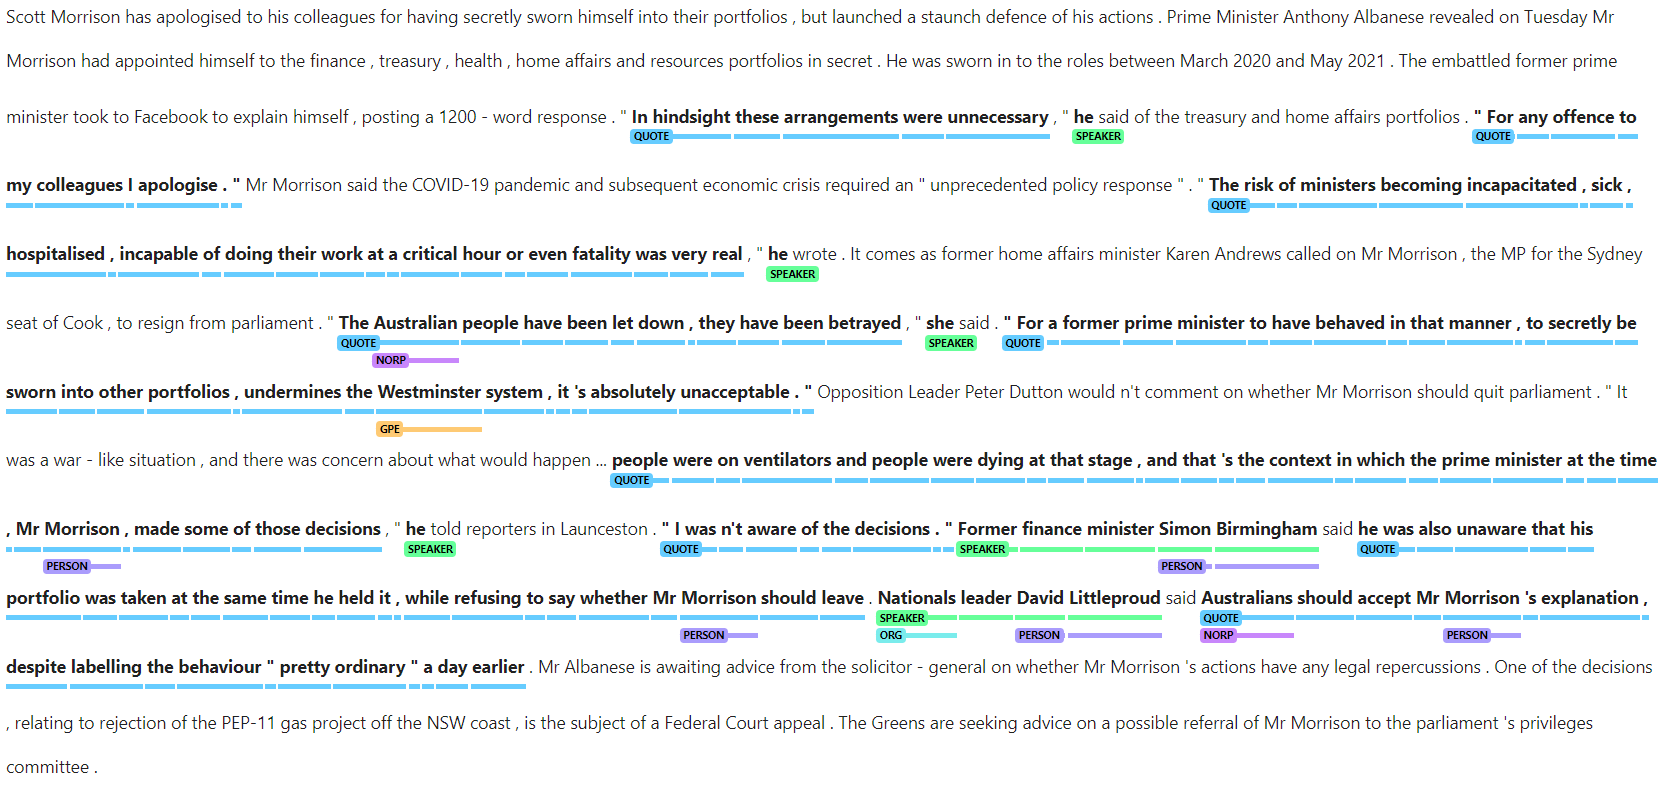
Learn more about the Quotation Tool for identifying and extracting quoted content, speakers and named entities from newspaper articles.
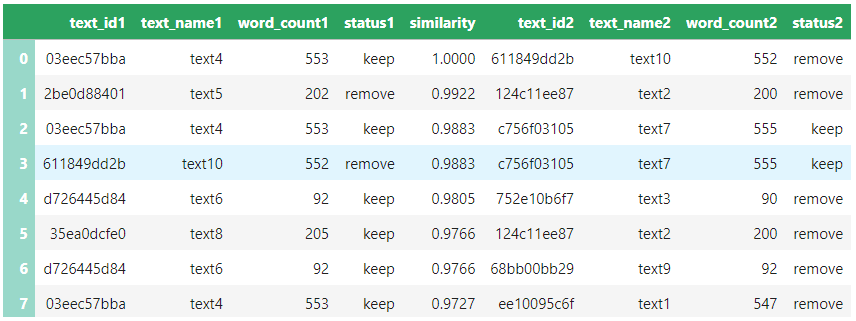
Introducing the Document Similarity Tool for comparing texts, identifying duplicated content and supporting the cleaning and building of text corpora.
The data which is being made accessible through LDaCA will contribute to the task of documenting language use and language behaviour in Australia. But what kinds of data does this include? Find out more in this post.
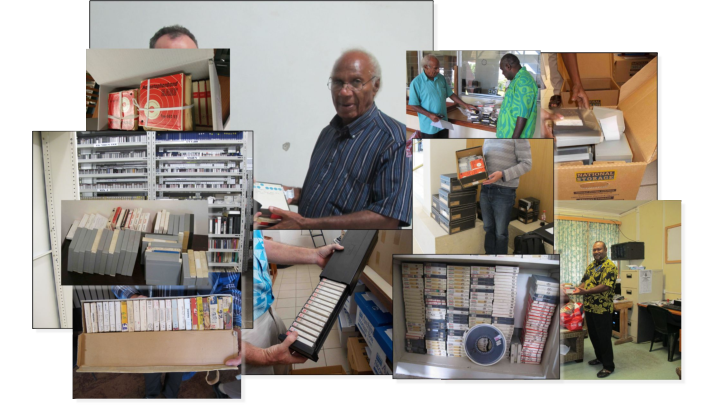
This presentation was delivered by Peter Sefton at eResearch 2022. The presentation examined the development and implementation of the RO-Crate metadata standard and a metadata profile (the Language Data Commons).
A write-up of a talk given at eResearch Australasia 2022, delivered by Peter Sefton, with some additional detail.
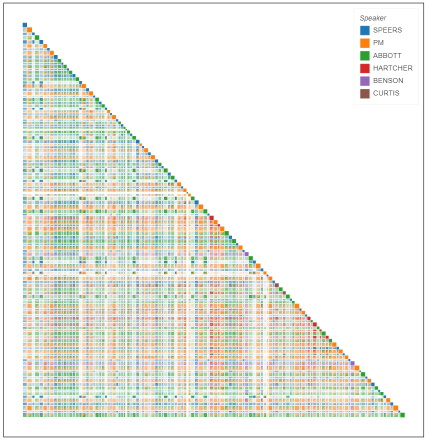
Discursis is communication analytics technology for analysing text-based communication data, participant interactions, topics and inter-speaker relationships.
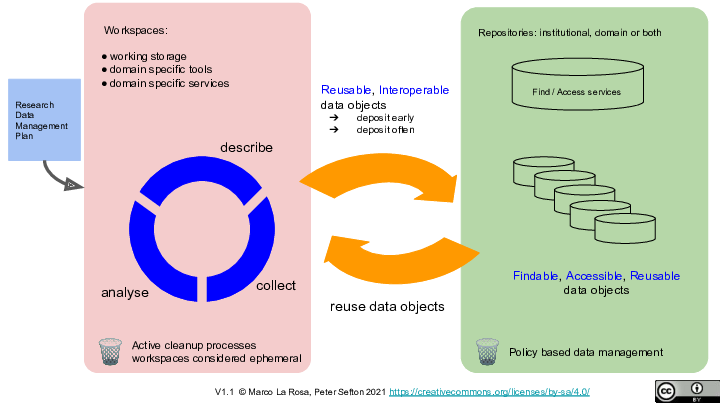
A presentation Peter Sefton gave to the Humanities, Arts and Social Sciences Research Data Commons and Indigenous Research Capability Program Technical Advisory Group on Friday 11 February 2022.
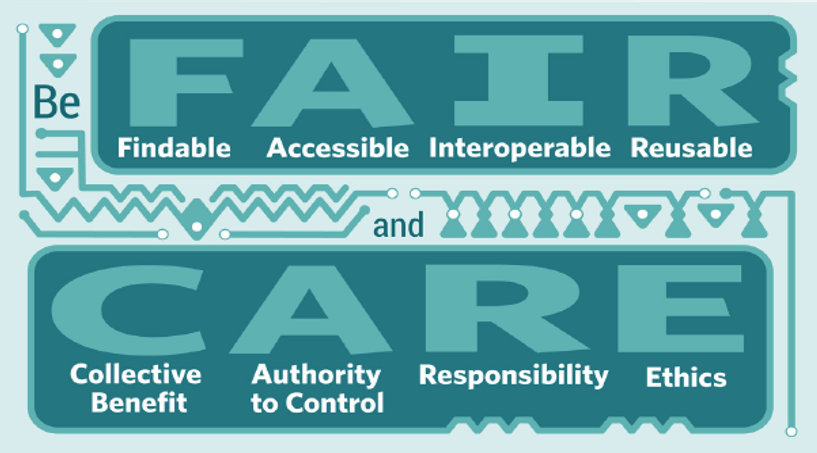
The FAIR — Findable, Accessible, Interoperable, Reuseable — and CARE — Collective benefit, Authority to control, Responsibility, Ethics — principles offer a best-practice approach to handling data. In this post, Simon Musgrave discusses how corpus linguists can work with these principles.